
AI & Tech
Explore Korean Pre-Korean Language Models (2)
This post continues from the previous post ‘Korean Pre-Korean Language Models (Korean Language Models) (1) ’ I recommend that you check it out first and then watch this content.
A look at Korean Pre-Korean Language Models (1) Go see
Similar to overseas, there are many examples of studying models in Korean based on Transformers learned in advance through large numbers of corpus. Various models such as KoBert, Korbert, HanBert, KoElectra, KoGPT, and Hyper CLOVA have been announced. In this article, I’ll first take a brief summary of the main models and features that have been released in chronological order, then sort them out by dividing them into encoder (encoder), decoder (decoder), and encoder-decoder (encoder-decoderModel, seq2seq) series.
Korean Language Model Chronicles
2019
Korbert(Korean Bidirectional Encoder representations from Transformers)
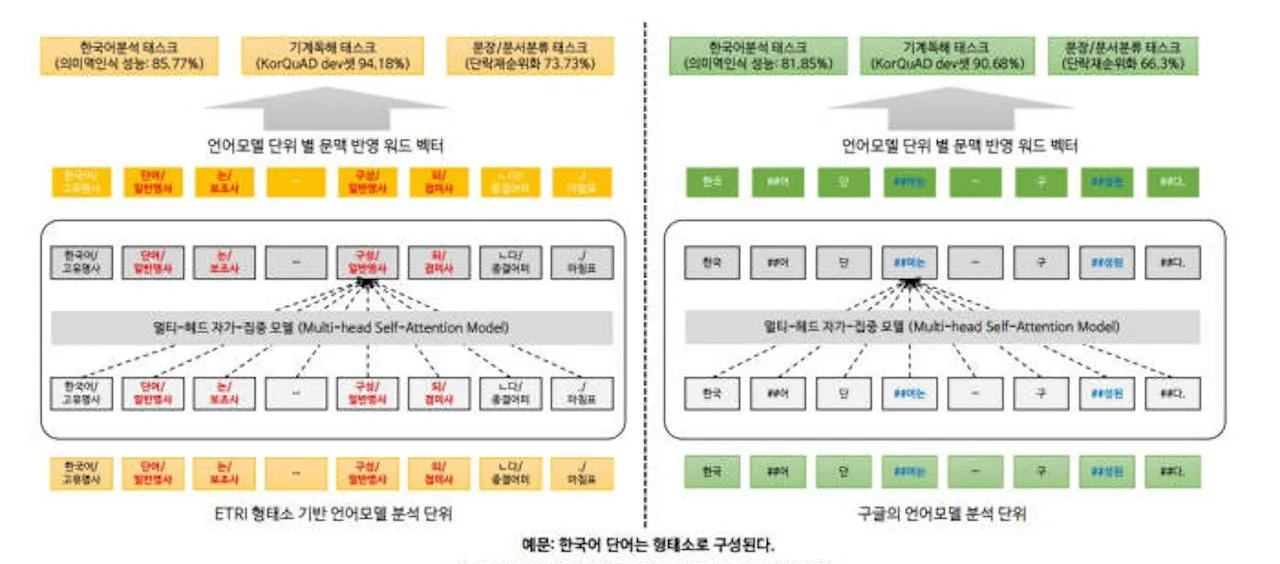
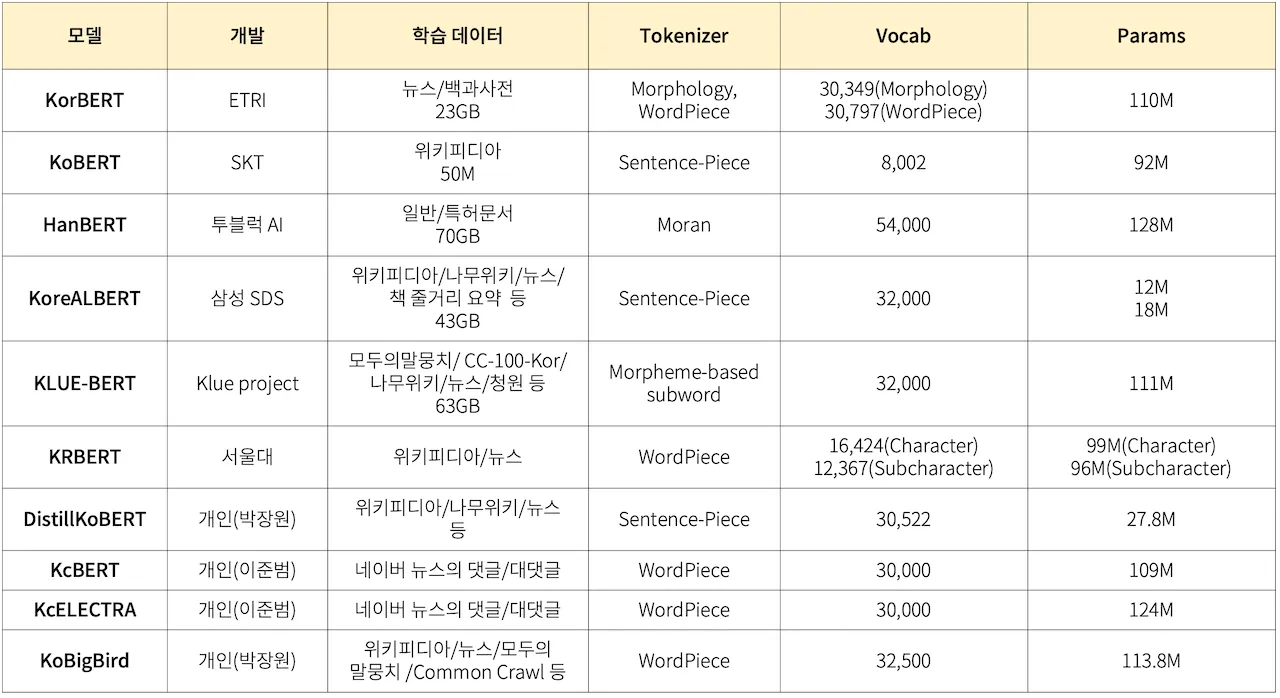
This is the first Korean language pre-learning model published by the Korea Institute of Electronics and Telecommunications Research (ETRI). It is a model trained with 23 GB of data extracted from Korean news and encyclopedias, and the parameter size is known to be 100M. Morpheme and WordPiece tokenizer were used, and the vocab (vocabulary) sizes were 30,349 (Morphemes) and 30,797 (WordPiece). It was announced that it showed superior performance than BERT because it reflected the characteristics of Korean, which is a crossword.
References
https://arxiv.org/pdf/1810.04805.pdf
https://medium.com/towards-data-science/pre-trained-language-models-simplified-b8ec80c62217
https://www.etnews.com/20190611000321
Kobert(KoreanBidirectional Encoder representations from Transformers)
It is a model learned from 50 million sentences collected from Wikipedia, news, etc. published by SKT. To reflect the characteristics of irregular language changes in the Korean language, a data-based tokenization (SentencePiece tokenizer) technique was applied, and the vocab size was 8002 and the model’s parameter size was 92M.
References
https://sktelecom.github.io/project/kobert/
https://github.com/SKTBrain/KoBERT
2020
HanBert(Hangul Bidirectional Encoder representations from Transformers)
This model was trained with 70GB of general documents and patent documents published by 2Block AI. It is known that they used a self-developed Moran tokenizer, and the vocab size is 54,000 and the model parameter size is 128M.
References
https://twoblockai.files.wordpress.com/2020/04/hanbert-ed8ca8ed82a4eca780-ec868ceab09cec849c.pdf
https://www.stechstar.com/user/zbxe/study_SQL/72557
https://github.com/monologg/HanBert-Transformers
KogPt2(Korean Generative Pre-Generative Transformer 2)
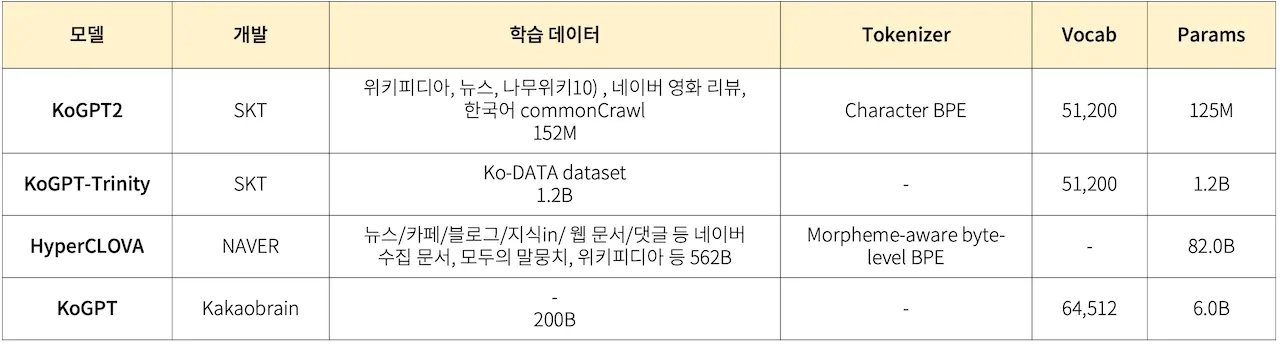
This is an open source-based GPT2 model learned in Korean announced by SKT. Like GPT2, it has a transformer decoder structure and uses next token prediction for learning. It is said that they learned with 152 M sentences extracted from various data such as Korean Wikipedia, News, Namu Wiki, and Naver movie reviews, and Tokenizer used CBPE (Character Byte Pair Encoding) and added emoticons and emojis frequently used in conversations to improve recognition ability. The vocab size is 51,200, and the base model size is 125 M parameters.
References
https://sktelecom.github.io/project/kogpt2/
https://github.com/SKT-AI/KoGPT2
KobArt(Korean Bidirectional and Auto-Regressive Transformers)
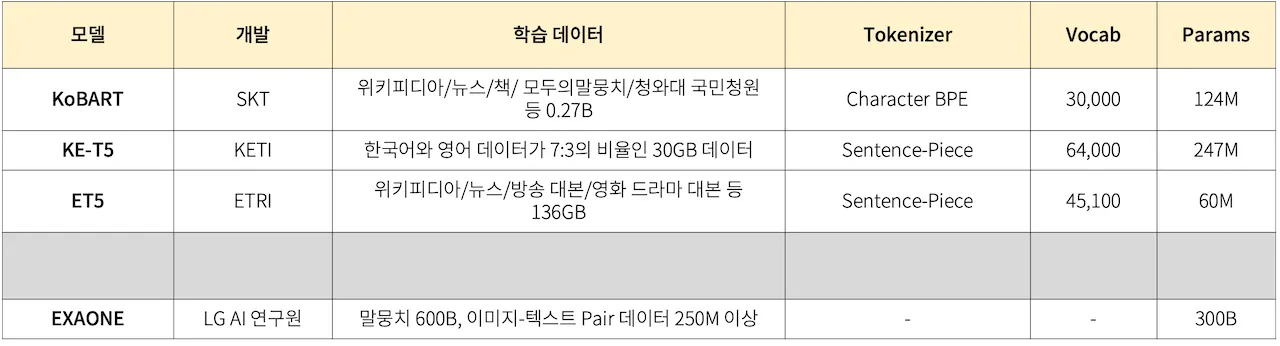
This is the third Korean version of the BART model released by SKT after the existing KobArt and KogPT2. KobART has an encoder-decoder structure similar to BART, and the denoising auto encoder method was used for pre-learning. I learned with more diverse 0.27B data than before, such as Korean Wikipedia, news, books, everyone’s horoscope, and the Cheongwadae National Petition.
References
https://arxiv.org/pdf/1910.13461.pdf
https://github.com/SKT-AI/KoBART
https://www.ajunews.com/view/20201210114639936
2021
KoreAlbert(Koreana Lite BERT)
It is a model released by Samsung SDS, and the Masked Language Model and Sentence-Order Prediction method were applied to pre-learning like ALBERT. We learned about 43 gigabytes (GB) of data, including Korean Wikipedia, Namu Wiki, news, and book plot summaries, and a 32,000 vocab size, and a 12M base model and an 18M large model were released.
References
https://www.samsungsds.com/kr/insights/techtoolkit_2021_korealbert.html
https://arxiv.org/pdf/2101.11363.pdf
https://arxiv.org/pdf/1909.11942.pdf
https://www.inews24.com/view/1316425
https://www.itbiznews.com/news/articleView.html?idxno=65720
https://www.itbiznews.com/news/articleView.html?idxno=66222
KE-T5
This is a Korean and English version of the model based on the Text-to-Text Transfer Transformer (T5) released by the Korea Institute of Electronics Technology (KETI). It is known that it was pre-trained using a mask-fill method similar to the T5 model using 93 GB of Korean and English corpus. The SentencePiece tokenizer was used in the preprocessing process, and the vocab size was 64,000. As a result, we released models of various sizes so that a total of 92.92 GB of Korean and English corpus can be selected and used in various ways according to model size and purpose of use.
References
https://arxiv.org/abs/1910.10683
https://huggingface.co/tasks/fill-mask
https://github.com/google/sentencepiece
https://koreascience.kr/article/CFKO202130060717834.pdf
https://zdnet.co.kr/view/?no=20210427130809
KOGPT-Trinity
It is known that it was learned with a 1.2B KO-data dataset built in-house using the model released by SKT. The size of the model is 1.2B, which is a significant increase compared to KogPt2, the vocab size is 51,200, and it was pre-trained with next token prediction.
References
https://huggingface.co/skt/ko-gpt-trinity-1.2B-v0.5
HyperClova
Using a large-scale model published by Naver, we learned vast amounts of data extracted from documents collected through Naver, such as news, cafes, blogs, knowledge in, web documents, and comments, and various documents such as everyone’s corpus and Korean Wikipedia. The data used for training consists of 561.8B tokens, and there are models of various sizes, such as 1.3B, 6.9B, 13.0B, 39.0B, and 82.0B.
References
https://www.etnews.com/20210525000052
https://tv.naver.com/v/20349558
https://arxiv.org/abs/2109.04650
KLUE-BERT
KLUE-BERT is a model used as a baseline in KLUE, which is the benchmark data, and was learned with 63 GB of data extracted from documents such as Everyone’s Corpus, CC-100-KOR, Namu Wiki, News, and Petitions. Morpheme-based Subword Tokenizer was used, the vocab size is 32,000, and the model size is 111M.
References
https://github.com/KLUE-benchmark/KLUE
KoGPT
It is a Korean model released by KakaoBrain and benchmarked GPT3. It is a 6B super-large model learned from 200B token Korean data, and the vocab size is 64,512.
References
https://github.com/kakaobrain/kogpt
https://huggingface.co/kakaobrain/kogpt
https://www.kakaocorp.com/page/detail/9600
http://www.aitimes.com/news/articleView.html?idxno=141575
ET5
Following T5, it was announced by ETRI, and it is a model that simultaneously pre-learned T5’s mask-fill and GPT3’s Next Token Prediction. I learned with 136 GB of data extracted from Wikipedia, newspaper articles, broadcast scripts, movie/TV series scripts, etc. It is 45,100 vocab size based on SentencePiece tokenizer, and the size of the model is 60M.
References
http://exobrain.kr/pages/ko/result/assignment.jsp #
https://www.etnews.com/20211207000231
EXAONE(ExpertAI for everyone)
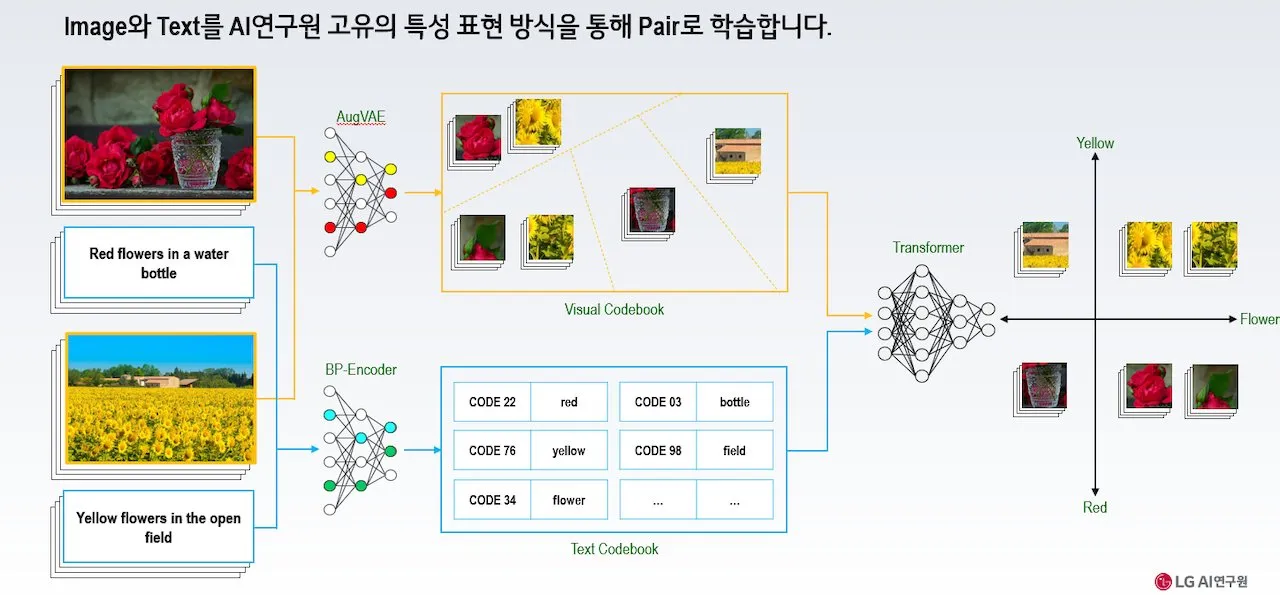
It is a multimodal (multimodal) model learned based on text, voice, and images published by LG AI Research. It has learned more than 250 million high-resolution images combining 600 billion corpus and language and images, and has approximately 300 billion parameters, which is the largest in Korea. It has multi-modality (multi-modality) ability to learn and handle various information related to human communication, such as converting language into images and images into language.
References
https://www.lgresearch.ai/blog/view?seq=183
https://www.aitimes.kr/news/articleView.html?idxno=23585
https://arxiv.org/pdf/2111.11133.pdf
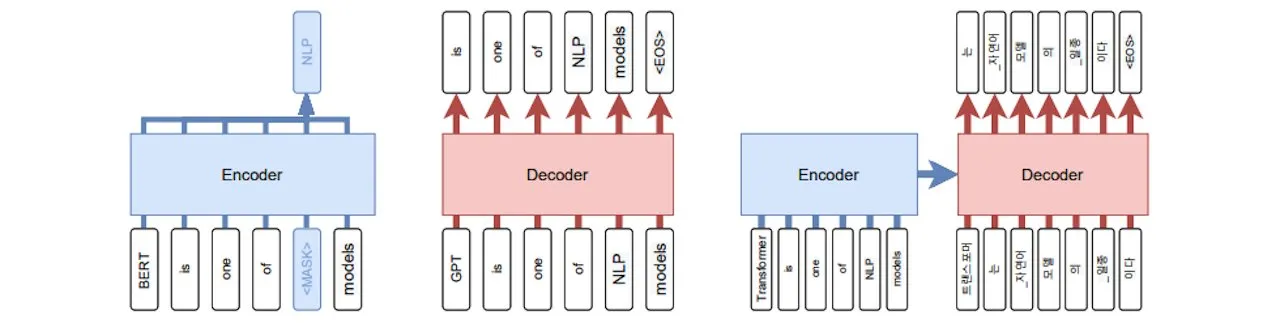
Three types of Korean language models
Encoder-Centric Models: BERT series
Decoder-Centric Models: GPT series
Encoder-Decoder Models: seq2seq family
Good content to watch together
View Korean Pre-Korean Language Models (1)
AI that became a linguistic genius, multilingual (Polyglot) model (1)
AI that became a linguistic genius, multilingual (Polyglot) model (2)
Can the open source language model BLOOM become the flower of AI democratization?
Why is artificial intelligence making Korean more difficult?
✏️콘텐츠 번역&현지화, 한 곳에서 해결하세요.
• 영상번역 툴 무료 체험하기
• 월간 소식지로 더 많은 이야기 읽어보기 💌